
|


The all-in-one intelligent cloud (Sponsored)
 |
Your app, live in seconds, for free. Railway’s push-button compute, storage, and networking is available immediately upon sign-up.
Humans and agents alike operate on one vertically integrated system including hardware, software, and a prompt-to-production experience.
Sign up with the link below for free cloud credits and let your agents cook.
This week’s system design refresher:
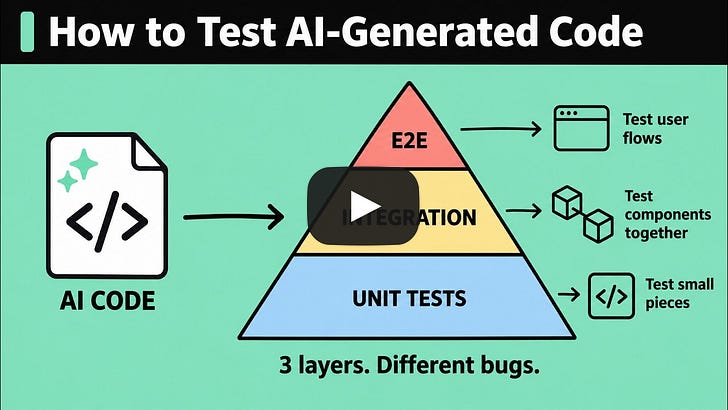
How to Test Your Code (Even When AI Writes It)
8 Chunking strategies for RAG-based agents
Google Translate: The Ideas Behind Neural Translation
Agent Skills, Clearly Explained
PostgreSQL versus MySQL
How to Test Your Code (Even When AI Writes It)
8 Chunking strategies for RAG-based agents
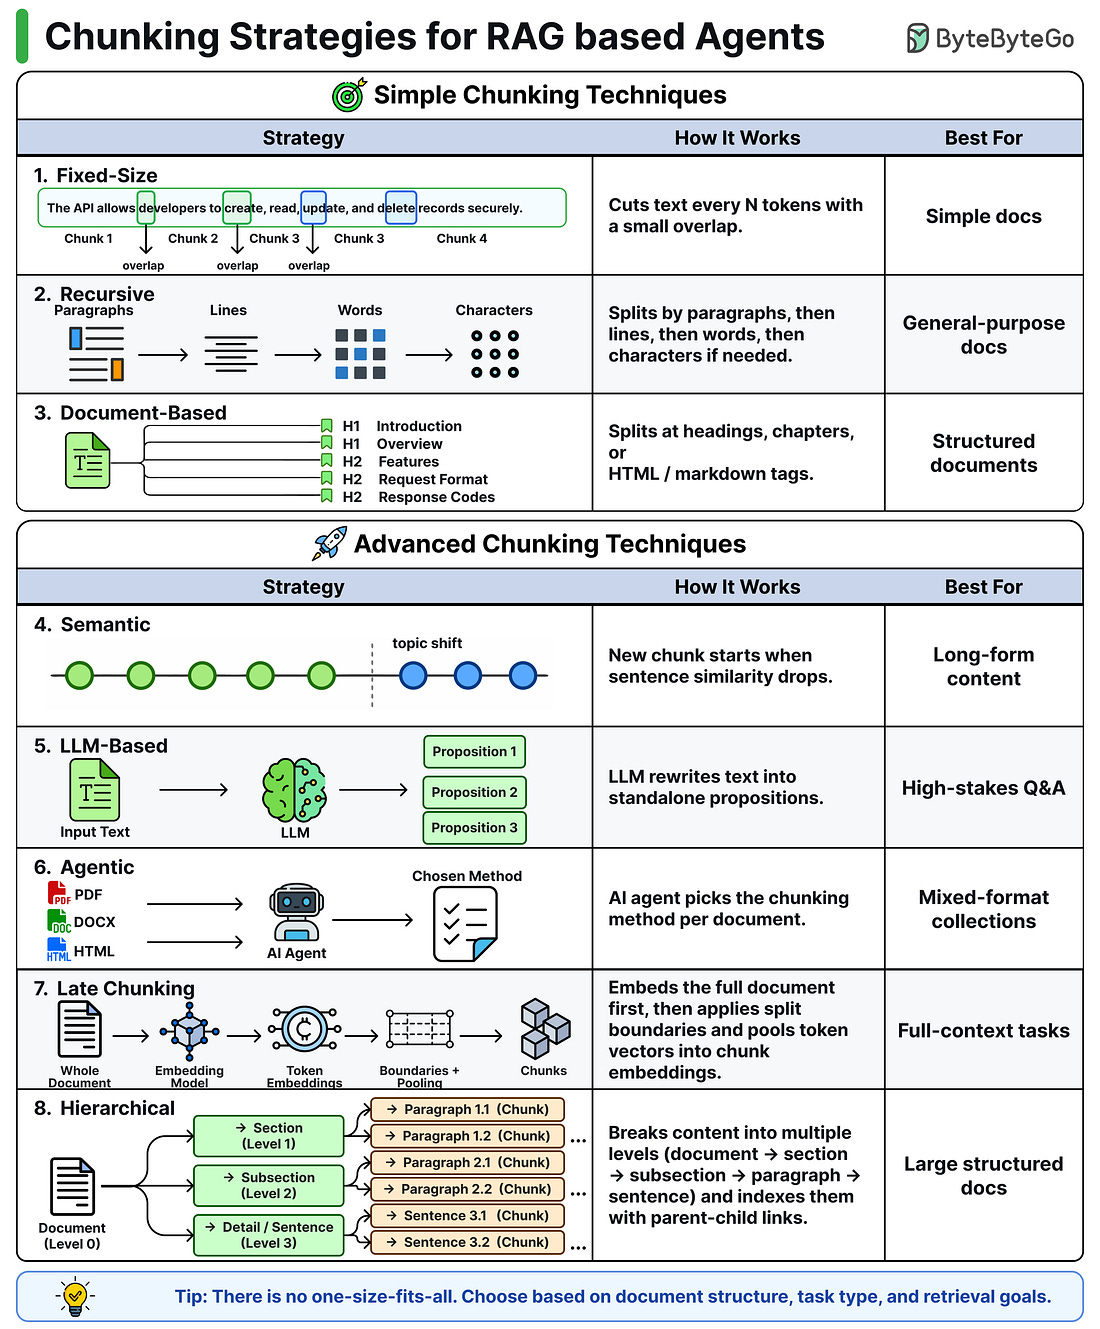 |
Fixed-Size: cuts text every fixed number of tokens, with a small overlap.
Recursive: splits on paragraphs first, falling back to lines then words and characters only when a piece is still too big.
Document-Based: splits wherever the document already marks a break, a heading, a chapter, an HTML tag, so a markdown file becomes one chunk per section on its own.
Semantic: embeds each sentence, checks its similarity to the one before it, and starts a new chunk when that similarity drops. This finds real topic shifts instead of guessing by length.
LLM-Based: asks an LLM to rewrite the text as standalone propositions, one idea per line, and turns each into a chunk, high quality but expensive across a large corpus.
Agentic: an AI agent reads each document, decides what it is (code, contract, table), and picks the chunking method for that file instead of one rule for everything.
Late Chunking: runs the full document through an embedding model, then applies normal split boundaries and mean-pools within each boundary to create chunk embeddings.
Hierarchical: breaks the document into layers, sections, paragraphs, then sentences
Over to you: which chunking strategy are you running in production?
Google Translate: The Ideas Behind Neural Translation
A simplified illustration of common techniques. Not an exact map of Google Translate’s current system.
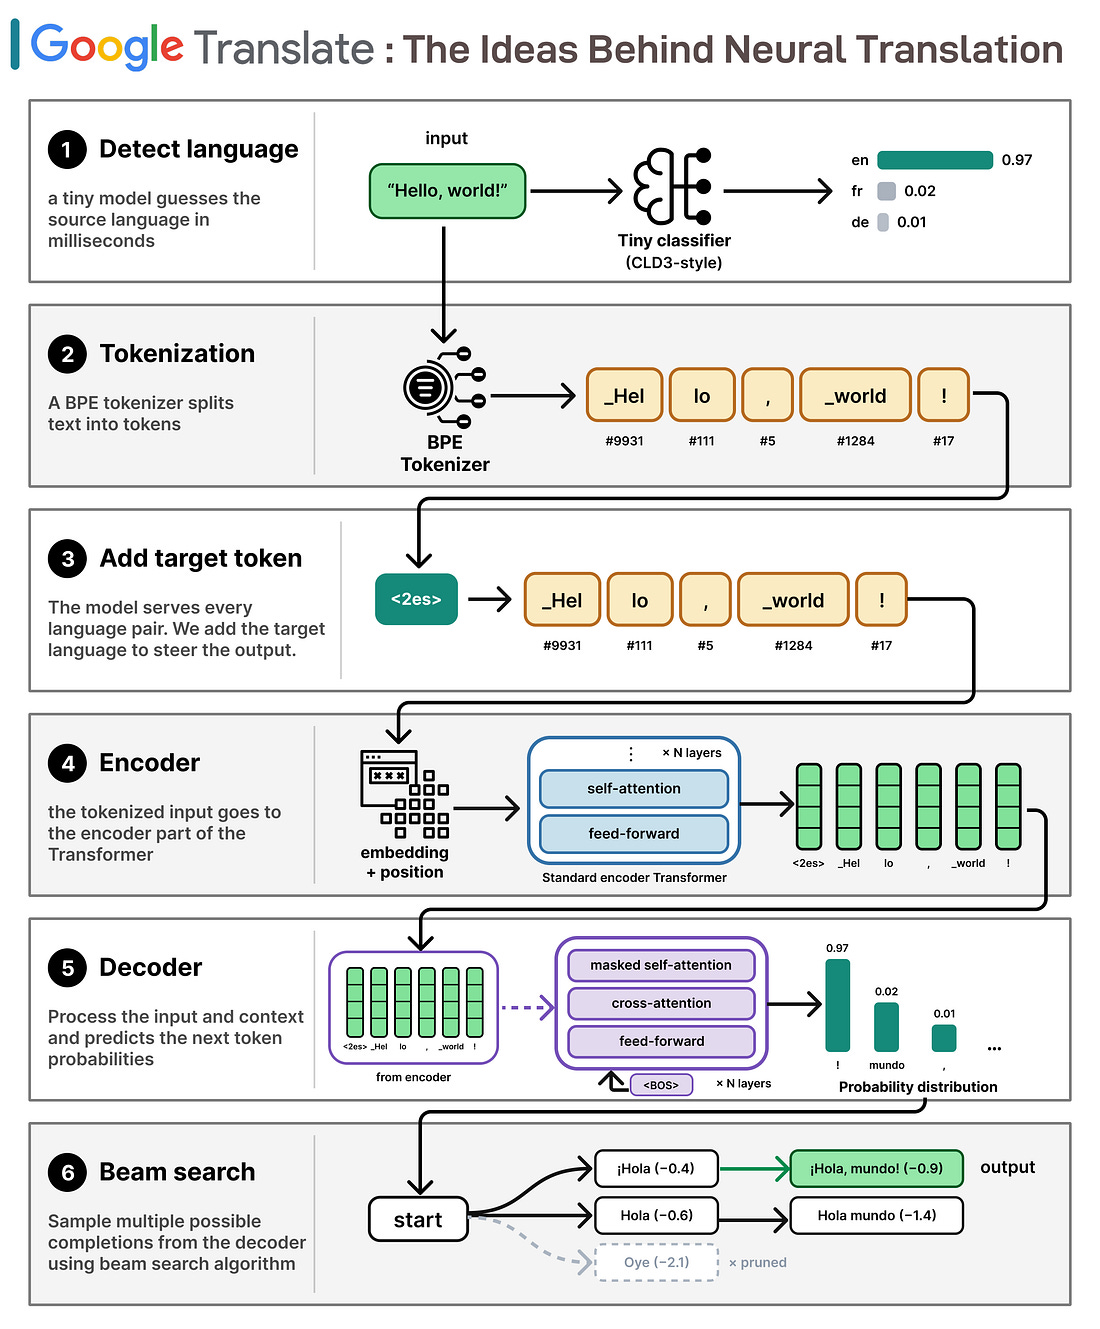 |
Detect language. A tiny classifier predicts the source language in milliseconds.
Tokenization. A BPE tokenizer splits the text into subword tokens, so the model can handle any word in any language.
Add target token. The model can handle every language pai